Data systems
A business database that answers in under a second
Prospecting across millions of American businesses usually means slow exports, stale lists and judgment calls nobody can retrace. Deep Space DataBase was built to make the evidence itself the product.
American businesses cataloged and continuously re-checked
12.5M
answer time for a filtered question against the full catalog
<1 sec
service lines scored per business, by rules, not a model
4
At a glance
12.5 million businesses, re-checked continuously, with every verdict traceable
A standalone data system that catalogs American businesses, re-checks them on a schedule and records each check as timestamped, append-only evidence. Verdicts are set by explicit rules so a human can always see why a business was flagged.
| Engagement | Internal data product, built end to end |
|---|---|
| Scale | Roughly 12.5 million business records |
| Stack | Cloudflare Pages and Functions, Turso (libSQL), R2, Python asyncio, Ollama, DuckDB |
| Team | One builder, design through operations |
Situation
The breaking point
- Bought lead lists go stale the week they arrive, and nobody knows which rows to trust.
- Manual research takes minutes per business, which caps how many businesses a day can even be looked at.
- Scores from opaque tools cannot be explained to the person acting on them.
- Evidence that is overwritten in place cannot be audited after the fact.
Approach
The build
Catalog the country's businesses, keep the facts fresh, and show where each one could use better service, without a black-box model deciding anything.
The system crawls and re-checks businesses continuously with Python asyncio pipelines, then writes each observation as append-only, timestamped evidence. Nothing is overwritten: a verdict can always be traced to the checks behind it and the moment they ran.
Verdicts are computed by explicit rules over the evidence, covering four service lines per business. Queries run against libSQL with DuckDB for analysis, so a filtered question across the full catalog returns in under a second.
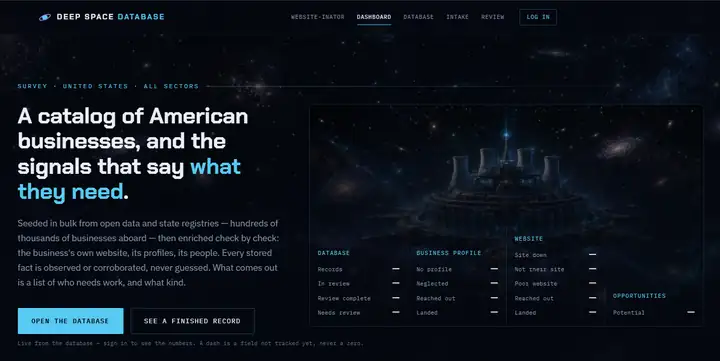
The moving parts
Under the hood
The core components that make the system work, and why each one matters.
Collection layer
Async crawling and re-checks
Python asyncio pipelines fetch and re-check business signals on a schedule, so freshness is a property of the system, not a manual chore.
Evidence store
Append-only, timestamped records
Every observation lands as immutable evidence in libSQL with R2 for bulk artifacts. History is kept, never rewritten.
Verdict engine
Rules, not a model
Explicit rules score each business across four service lines, so every flag is explainable and reproducible.
Query surface
Sub-second answers
A Cloudflare Pages front end over libSQL and DuckDB turns a filtered question into an answer in under a second.
What shipped
- Continuous collection and re-check pipelines
- Append-only evidence store with full history
- Rule-based verdicts across four service lines
- Sub-second query surface over the full catalog
- Analysis tooling on DuckDB for bulk questions
Plugged into
- Cloudflare Pages and Functions
- Turso (libSQL)
- R2 object storage
- Python asyncio pipelines
- Ollama and DuckDB
The safety rails
- Verdicts set by explicit rules a person can read, never an unexplainable score
- Append-only records, so history cannot be quietly rewritten
- Timestamps on every observation, so staleness is visible, not hidden
- Public-signal data only, gathered and stored responsibly
Outcomes
The payoff
Prospecting questions that took a research session now take a second.
Every flag can be defended, because the evidence and rules behind it are kept.
Freshness is automatic: the system re-checks itself instead of waiting on a person.